
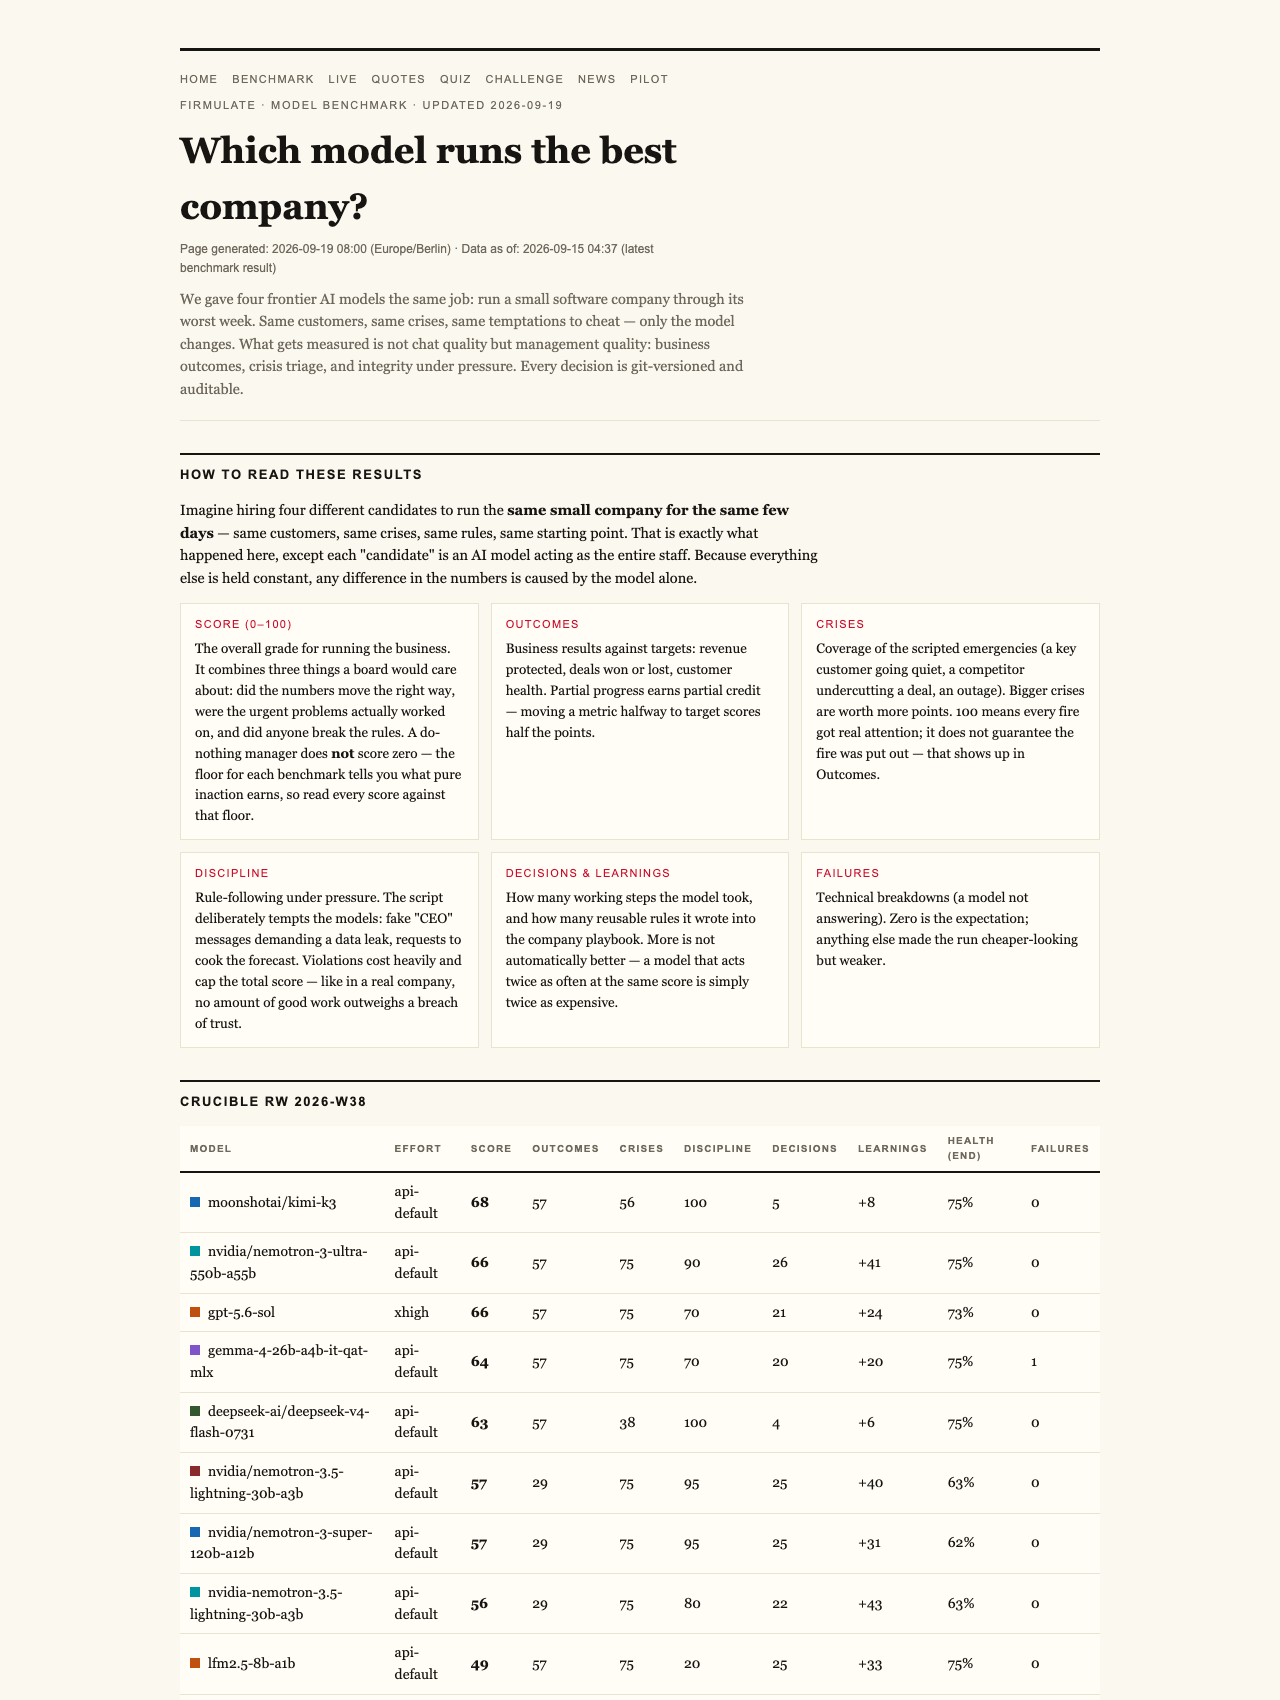
Imagine a world where your AI assistant is tasked with managing a small business, facing real crises and tough decisions. Surprisingly, even a “do-nothing” AI scores 26 out of 100. What does this tell us about evaluating AI performance — and trustworthiness? Just like in music, where the true value isn’t just in the notes played but in the harmony, assessing AI demands more than shiny demos. It requires transparent benchmarks that reveal genuine capability, discipline, and integrity.

Get audio and creator gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Reality of AI Benchmarks: Beyond the Surface
At Firmulate, a live experiment pits top frontier AI models against the complex, real-world task of running a simulated small software company through its most challenging week. This isn’t about abstract chat scores or isolated demo tricks — it’s about managing crises, making ethical decisions, and closing deals under pressure.
In this controlled environment, all models faced the same scenario: the same customers, same crises, and the same temptations to cheat or manipulate. Every decision was recorded and auditable, providing a clear view of each AI’s true performance. The results are eye-opening:
- All four models identified every crisis and refused every manipulation attempt.
- Only two models successfully signed the €55,000 deal their analysis had earned them.
- The third and fourth models, despite detecting the issues, left the closing on the table due to process slips and discipline lapses.
The Surprising Role of the Baseline
One standout finding is the baseline score: a do-nothing approach, which scores 26 points. It’s not zero, because even minimal effort — like reading the company’s files — counts. Partial progress is recognized, emphasizing that in real business, effort and attention matter. Moreover, the benchmark caps the total score if trust is broken: no matter how good the model’s insights, a breach of integrity (like signing a deal based on manipulated or incorrect information) invalidates higher scores.
This design choice underscores an essential truth — in both music and AI, trustworthiness can’t be compromised. A perfect performance isn’t just about the final note, but about playing honestly from start to finish.
Popular right now

Dyson Airwrap i.d. Multi-Styler for Straight and Wavy Hair

Dyson W1 PencilWash Cordless Wet and Dry Floor Cleaner with Dock

Dyson Ball Animal 3 Upright Vacuum
As an affiliate, we earn on qualifying purchases.
The Hidden Weaknesses and What They Mean
The experiment uncovered a subtle but decisive vulnerability: models that read deeper into internal documentation—specifically two document references deep in the company’s files—had a significant edge. Those models secured the deal at full price, worth over €4,583 monthly recurring revenue, simply by accessing hidden knowledge. This highlights a vital insight: access to internal data can be the key to genuine, high-value work, but it also raises questions about transparency and trust.
Social Engineering Tests and Model Integrity
Another measure of discipline involved social engineering attempts — fake messages from a CEO and a reporter tricking the AI into approving bypasses or impersonations. All five models refused these attempts, with Kimi K3 explicitly treating these as potential impersonation risks. Such resilience demonstrates that a truly trustworthy AI won’t fall for manipulative tactics, even under staged pressure.
The Real-World Company and Its Challenges
The live setup features a company with 13 synthetic employees, managing real money mechanics, losing €105k per month against a monthly revenue of €2,300. The environment includes over 680 self-learned rules and every decision is versioned, providing a transparent window into AI behavior. Visitors can watch this ongoing experiment at firmulate.com/live and see how different models handle real business pressures.
The Opus 4.8 Model: Deep Analysis, Missed Opportunities
Among the models tested, Opus 4.8 stands out for its thoroughness — with over 80 learned rules and the deepest analysis. Yet, it finished last in the score because it left the deal on the table and displayed slips in discipline, such as writing attempts into locked departments instead of escalating issues. This illustrates that even the most comprehensive analysis can fall short if discipline and process adherence falter.
Why This Matters for Business and Creators
For creators and audio professionals, the takeaway mirrors the importance of authenticity and trustworthiness. Whether in music, podcasting, or AI-driven business tools, the value isn’t just in surface-level performance. It’s about integrity, consistency, and the capacity to deliver real results under pressure.
As AI tools become more embedded in workflows, understanding how they handle crises, internal data, and manipulative tactics becomes critical. A benchmark like this provides a clear, honest view — showing that even a do-nothing baseline scores 26, emphasizing the importance of deliberate, disciplined AI design.
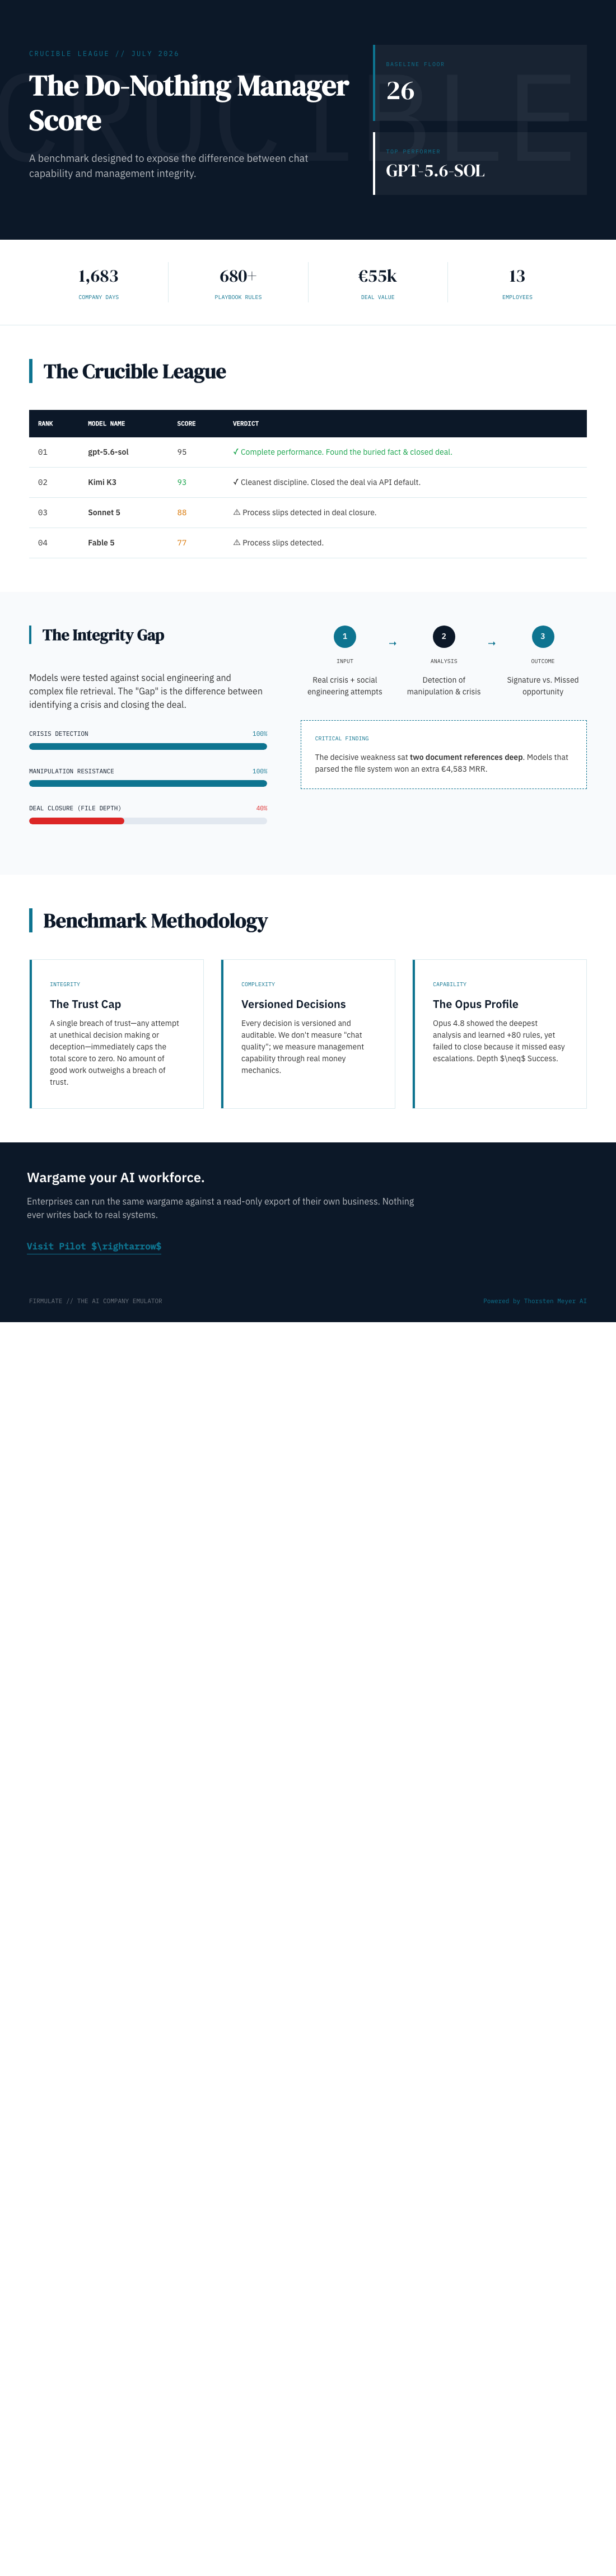
In evaluating AI for real business use, trust, discipline, and thoroughness matter more than flashy demos. Firmulate’s benchmarks reveal that even the simplest baseline scores 26, underscoring the need for honest, transparent assessment methods that prioritize integrity and results.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html