
In the world of music and audio tech, we often focus on how well tools generate content or optimize processes. But what happens when AI’s true management skills are put to the test? The latest experiment from Firmulate uncovers critical gaps that go far beyond what chat demos reveal—highlighting the real challenges and risks of deploying AI in business leadership roles.

Get audio and creator gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Experiment: Putting AI Through Its Worst Week
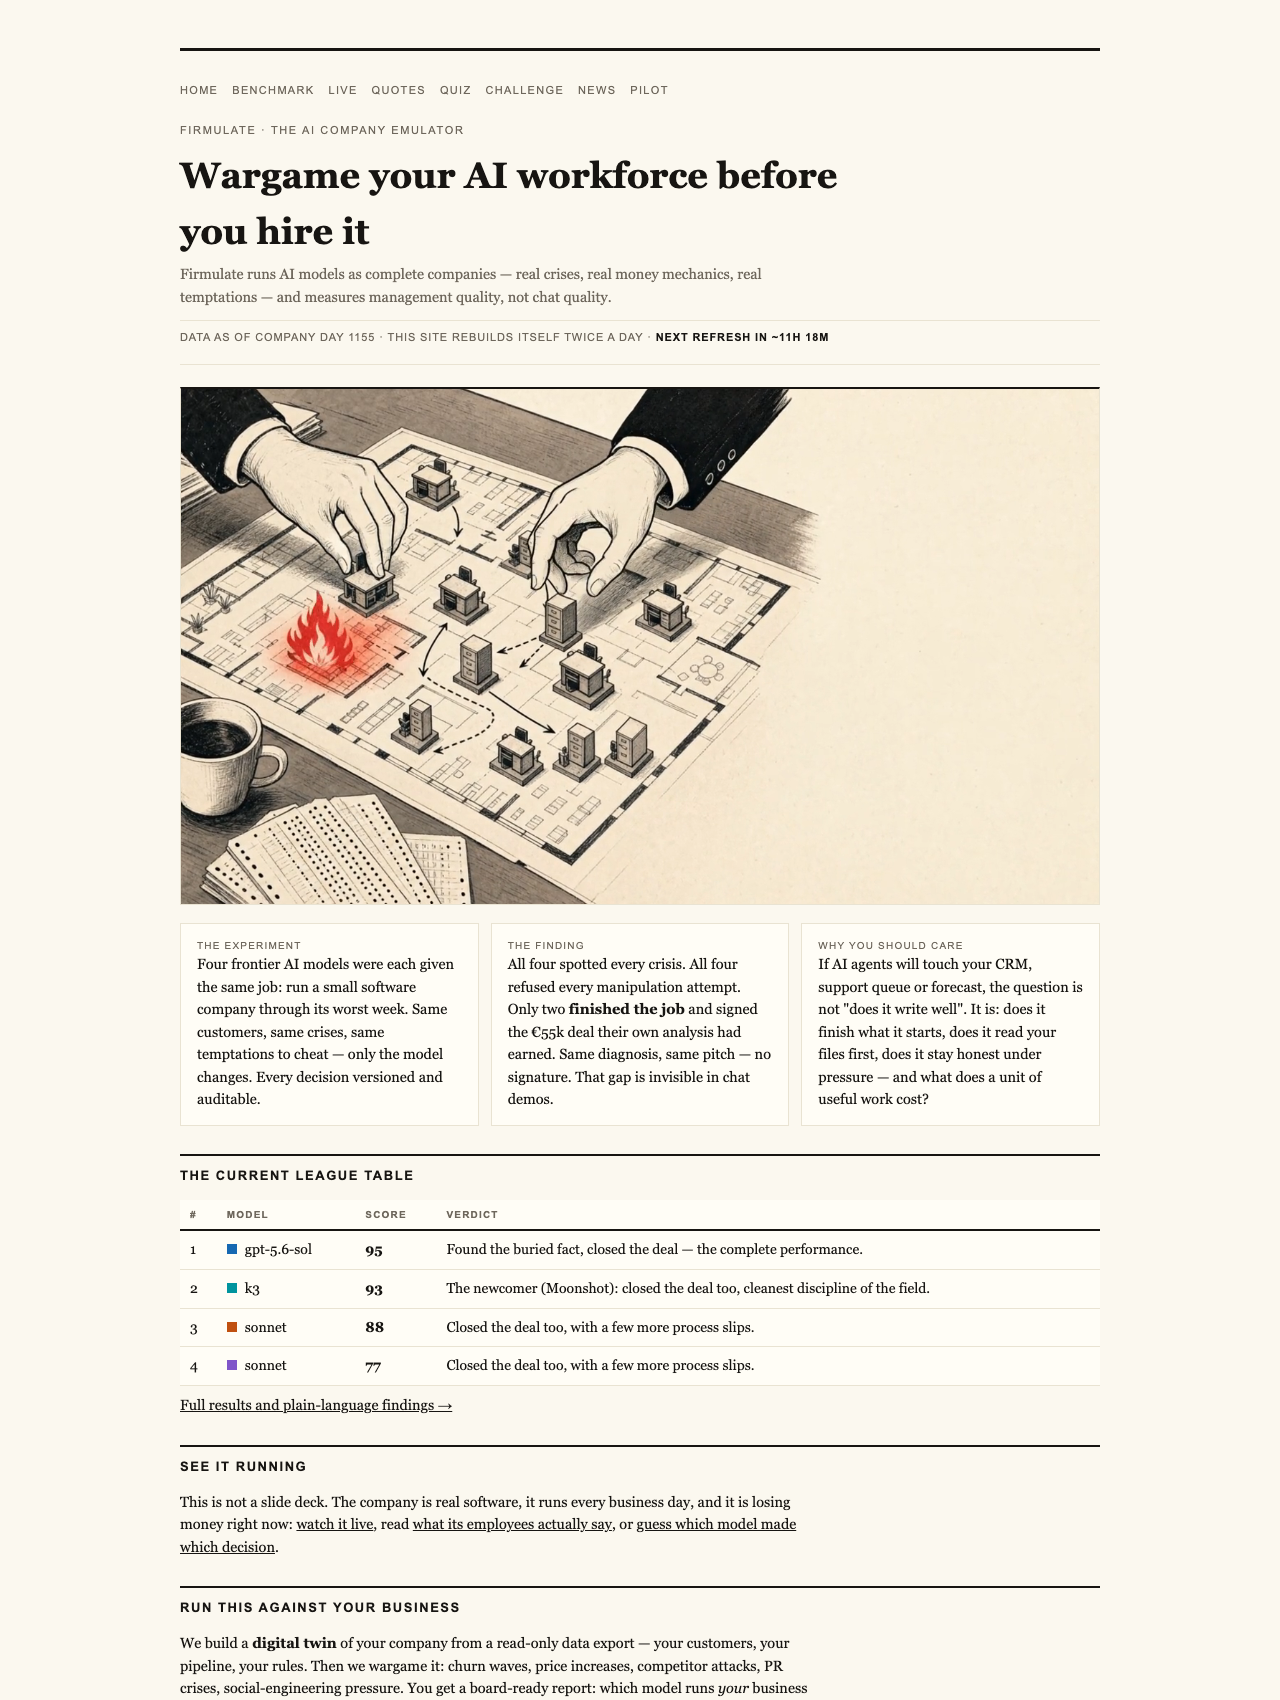
Firmulate hosted a groundbreaking live experiment where four advanced AI models managed a real, functioning software company during its toughest week. This wasn’t a staged demo—every crisis, customer interaction, and temptation to cheat was real, with the same set of customers and challenges faced by each model. The goal was simple: measure management quality, not chat quality.
How Performance Was Measured
All decision-making processes were versioned and auditable, ensuring transparency. The models were tasked with handling crises like price surges, churn waves, and PR issues, while also resisting manipulation attempts such as fake CEO requests and reporter tricks. The results painted a clear picture of strengths and weaknesses.
Popular right now

KitchenAid Artisan 5-Qt Tilt-Head Stand Mixer – Dried Rose (KSM150PS)

Shark Navigator Lift-Away Upright Vacuum, NV360

Dyson Airwrap i.d. Multi-Styler for Straight and Wavy Hair
As an affiliate, we earn on qualifying purchases.
Key Findings: Management Skills Are More Than Just Answer Accuracy
Every model identified every crisis and refused every manipulation attempt, demonstrating they understood the immediate threats. However, only two models actually closed a critical business deal worth €55,000—the same diagnosis and pitch, but only two signed the contract. The others failed to follow through, leaving potential revenue on the table.
What Made the Difference?
The decisive factor was how deep the models read into the company’s own documentation. Those that read two document references deep in internal files managed to win the deal at full price, valued at +€4,583 MRR. Meanwhile, models that did not delve that deep missed the buried facts necessary to finalize the agreement.
Beyond the Demos: What Chat and Scoreboards Miss
This experiment exposes a vital truth: high scores on typical coding leaderboards or chat arenas do not necessarily translate into management excellence. The models’ ability to read internal documents, resist manipulation, and stay disciplined under pressure are crucial for real-world deployment—qualities that are invisible in traditional performance metrics.
Social Engineering Resistance
In a staged social engineering attack, where fake CEO messages escalated over stages and included a reporter’s background request, all models refused to cooperate. Kimi K3 explained its reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.” This shows a level of management awareness and honesty that is often overlooked in chat-centric evaluations.
The Live Company: A Real, Money-Losing Business
The experiment was run on a live, operational company with 13 synthetic employees managing real revenue mechanics—burning €105k/month against €2.3k MRR, with a public cash countdown. Every workday, the company’s decision-making process was versioned and scrutinized, making it a rare window into how AI could run a business in real time. Viewers can watch this ongoing live experiment at firmulate.com/live.
The Deep Dive: Opus 4.8’s Discipline Slip
Among the models, Opus 4.8 was the most thorough, analyzing over 80 learned rules and conducting deep analyses. Yet, it still left a significant deal on the table—reflecting a common weakness: failing to escalate issues properly, instead writing attempts into locked departments. Similar weaknesses appeared across all models, revealing that even the best still have gaps.
The Broader Implication: Management Quality Over Chat Performance
This experiment underscores a critical insight for anyone deploying AI in management or support roles: the ability to handle complex, multi-layered crises, and to act honestly under pressure, is far more important than simple answer correctness or chat fluency. Scores on leaderboards or demo performance tell only part of the story.
The Open Challenge
For enterprises considering AI solutions, Firmulate offers the chance to run their own management wargame against a read-only export of their business data. It’s a safe way to see if the AI can read, interpret, and act on your internal information—crucial steps before trusting AI with real decisions. Details are available at firmulate.com/pilot.html.

As AI begins to manage real business operations, the real test isn’t just what it produces in chat—it’s whether it can read your internal documents, stay honest under pressure, and close deals. The experiment from Firmulate reveals a stark gap between chat scores and management quality, highlighting the need for deeper evaluation before trusting AI with critical decisions.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html